
What 100 Vinted Parcels Taught Me About Data Management and Indexing Techniques
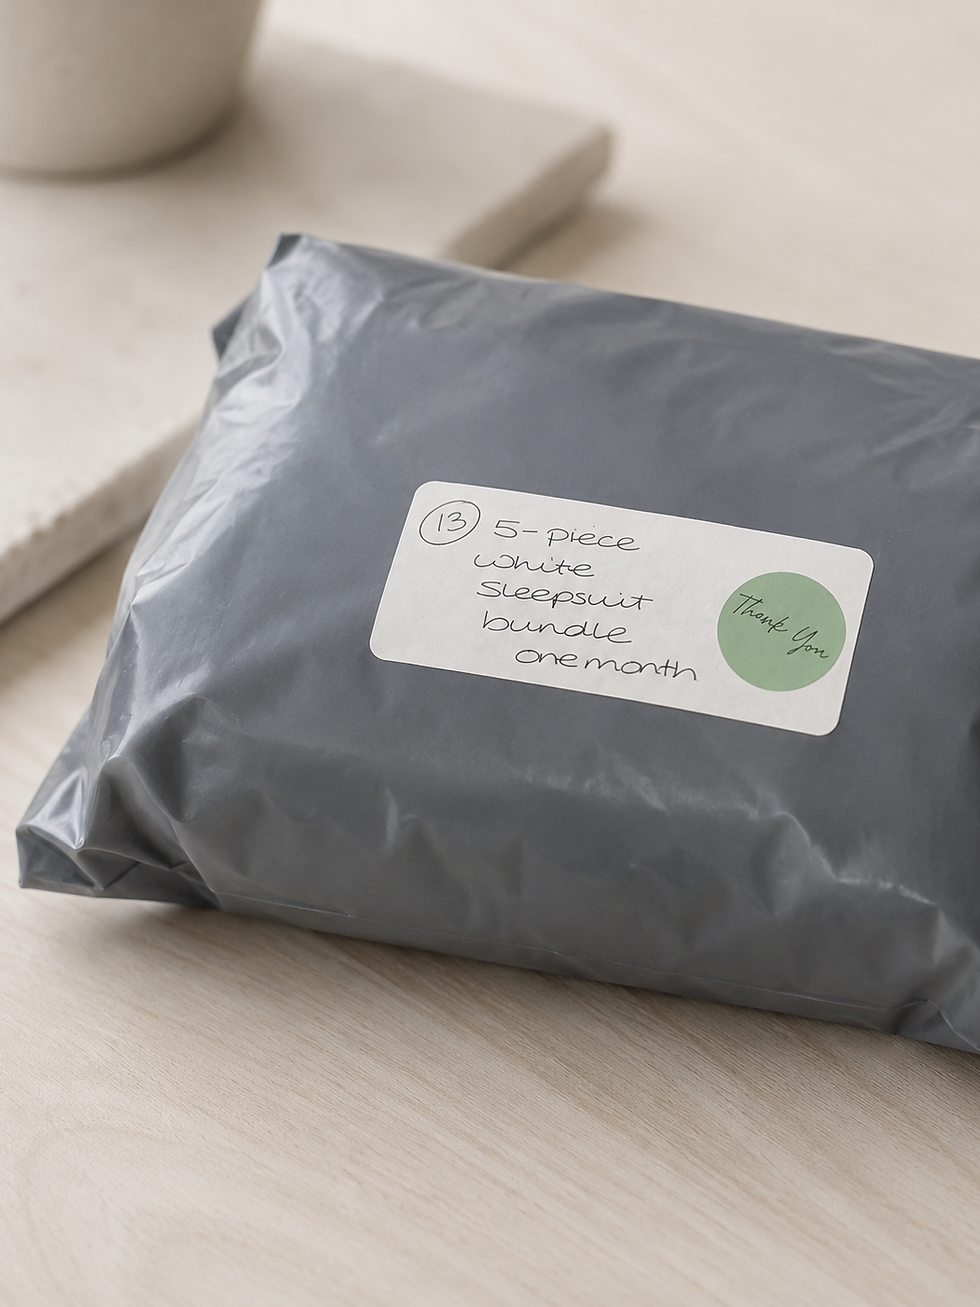
There are some lessons you learn in a meeting room. This one arrived in about 100 grey Vinted parcels.
Michelle had been remarkably organised. Every item was logged in a spreadsheet, each one had a number, and the corresponding number went on the parcel. Simple, sensible and — in theory — very easy to use.
Then our toddler decided to ‘help’ by jumping into the parcels and mixing up Michelle’s carefully separated CHECKED and NOT CHECKED piles.
I was feeding the baby, watching Michelle work her way through what now looked less like an collection system and more like a small grey landslide, when I said:
This is a real-life metaphor for why data management and indexing techniques is so important.
But after thinking about it, the more interesting part of the story isn’t really the collection. It’s the indexing.
Because the question wasn’t: do we have parcel 88? We knew we did. The question was: how quickly can we find parcel 88 when the amount of stuff has grown beyond the point where simply looking through everything is sensible?

When ten parcels don’t need an index
Imagine you have ten Vinted parcels in one bag and somebody asks for parcel number 7.
You could just empty the bag, check each parcel and stop when you find it. It is not sophisticated, but with ten items it is probably completely fine.
In computing terms, that is essentially a linear scan: start at the beginning and keep checking until you find the thing you want.
The problem appears when ten becomes 100. Or 1,000. Or 10 million records in a database.
The data is still there. Searching everything still works. It just starts taking too long.
That is where indexes become useful.
An index is an extra structure that helps you get to the right data faster. The trade-off is that the index itself needs storage, maintenance and updating when the underlying data changes.

Option 1: ‘Parcel 88 lives here’ — a hash index
The most obvious fix would be to give every parcel an exact location.
Parcel 88 → Box B, shelf 3.
Parcel 42 → Box A, shelf 1.
Now, when somebody asks for parcel 88, you do not search the parcels at all. You look up 88 and go straight to its location.
That is a useful way to think about a hash index. A hash index is excellent when the question is an exact lookup: ‘give me the record for this exact key’.
Where it is less helpful is when the question becomes: ‘give me everything between parcel 80 and parcel 100’. Hashes are designed for exact lookups, not naturally ordered ranges.
Option 2: Put the parcels in order — range and B-tree indexing
Another option would be to physically organise the parcels by number.
1–100 over here. 101–200 over there. Within each group, keep them in order.
Now if I ask for parcel 188, you know roughly where to go. And if I ask for every parcel from 180 to 200, that is easy too.
This is the idea behind ordered indexes such as B-tree indexes, which are commonly used for range queries. They keep keys in an ordered structure so systems can efficiently find one value or walk through a range of values.
The trade-off? Keeping things ordered takes work. New data arrives, entries move, structures split or rebalance, and that maintenance has a cost.
Option 3: ‘Show me every sleepsuit’ — an inverted index
Now imagine Michelle stops asking for a parcel number and instead says: ‘Find every parcel containing sleepsuits’ or ‘show me everything aged 0–3 months’.
An index based only on parcel number is suddenly not the most useful thing.
Instead, you could build a reverse list:
sleepsuit → parcels 12, 18, 44, 88
0–3 months → parcels 7, 22, 44, 61
F&F → parcels 2, 17, 35, 88
That is the basic idea behind an inverted index: rather than storing ‘record → words’, you maintain a mapping from ‘word or attribute → matching records’.
It is one of the reasons search engines and text-search systems can find relevant records without reading every document from start to finish each time.
Again, there is a cost. Every time the underlying information changes, the inverted index may need updating too.
Option 4: ‘Definitely not in this bag’ — a Bloom filter
This is where it gets slightly more interesting.
Imagine the 1,000 parcels are split across ten large bags. Before opening every bag, it would be useful to know whether parcel 88 could even be inside it.
A Bloom filter is a very compact probabilistic structure that can answer a membership question quickly.
For our parcels, each bag could have a Bloom filter representing the parcel numbers inside it.
Ask, ‘Could parcel 88 be in this bag?’ and the filter gives you one of two useful answers:
Definitely not — skip the bag entirely.
Possibly — it might be there, so check properly.
A Bloom filter can produce false positives — it can say ‘possibly’ when the item is not actually there — but, when implemented correctly, it does not produce false negatives. If it says ‘definitely not’, you can safely move on.
That makes Bloom filters useful as a first-pass filter when checking the real data would be expensive.
Option 5: Index the way people actually ask questions — composite indexes
What if the common question is not just ‘0–3 months’ or ‘F&F’, but ‘F&F sleepsuits, 0–3 months, not yet sold’?
Databases can also build composite indexes across multiple fields.
They can be extremely effective when the index matches the way the system is queried. But the order of the indexed fields matters, and an index designed for one query pattern can be far less useful for another.
Which brings us to the point I was actually trying to make while Michelle was underneath a mountain of parcels.
More indexes are not automatically better
If indexes make searches faster, it is tempting to index everything.
Unfortunately, that creates another problem.
Indexes consume storage. They take time to build. They have to be maintained. Inserts and updates may become more expensive because every relevant index also needs to change.
In parcel terms, imagine maintaining five different filing systems for the same 100 parcels every time Michelle sells or adds one. At some point, the organisational system becomes more work than the thing it was supposed to organise.
That is why the right answer is rarely ‘add more indexes’.
The right index starts with the question
The best indexing strategy depends on how you are planning to use the information.
Are you normally looking up one exact value? A hash-style lookup may make sense.
Do you need ordered or range queries? An ordered/B-tree-style index is more useful.
Are people searching by words, categories or attributes? An inverted index may fit better.
Do you need to cheaply rule out places where data definitely is not? A Bloom filter can help.
Do your common queries combine several fields? A composite index may be worth the maintenance overhead.
And that decision also depends on how the data arrives, how often it changes, how much of it there is, and how much management overhead you are willing to endure.
There is no universally ‘best’ index. There is only an index that is useful for the access pattern you actually have.
Why this matters outside a pile of Vinted parcels
The same trade-offs appear everywhere in technology: databases, search platforms, logs, product catalogues, analytics systems and large data platforms.
When something feels slow, the instinct can be to throw more compute at it or buy another tool. Sometimes the real problem is much simpler: the information is stored, but it is not structured for the way people are trying to retrieve it.
That is why understanding the data, the query patterns and the operational overhead matters before choosing a technical solution.
Where M&M Digital Services comes in
This is the part of IT I enjoy: taking something that sounds unnecessarily technical and turning it into a practical decision about how a business actually works.
At M&M Digital Services, we can help businesses understand how their data and systems are being used, where performance or complexity is creeping in, and what architecture, indexing or process changes would genuinely make things simpler.
Sometimes the answer is a new platform. Sometimes it is a better data model. Sometimes it is an index. And sometimes it is simply stopping people from searching all 1,000 parcels every single time.
Technology should make finding the right thing easier — not turn it into a family-wide search operation.
Mark
M&M Digital Services


Comments